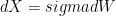Hedgehogs and foxes: Or, a day in the life of a quant

I must state at the outset that this post is inspired by the second chapter of Nate Silver’s book The Signal and the Noise. In that chapter, which is about election forecasting, Silver draws upon the old Russian parable of the hedgehog and the fox. According to that story, the fox knows several tricks while the hedgehog knows only one – curling up into a ball. The story ends in favour of the hedgehog, as none of the tricks of the unfocused fox can help him evade the predator.

Most political pundits, says Silver, are like hedgehogs. They have just one central idea to their punditry and they tend to analyze all issues through that. A good political forecaster, however, needs to be able to accept and process any new data inputs, and include that in his analysis. With just one technique, this can be hard to achieve and so Silver says that to be a good political forecaster one needs to be a fox. While this might lead to some contradictory statements and thus bad punditry, it leads to good forecasts. Anyway, you can know about election forecasting from Silver’s book.

The world of “quant” and “analytics” which I inhabit is again similarly full of hedgehogs. You have the statisticians, whose solution for every problem is a statistical model. They can wax eloquent about Log Likelihood Estimators but can have trouble explaining why you should use that in the first place. Then you have the banking quants (I used to be one of those), who are proficient in derivatives pricing, stochastic calculus and partial differential equations, but if you ask them why a stock price movement is generally assumed to be lognormal, they don’t have answers. Then you have the coders, who can hack, scrape and write really efficient code, but don’t know much math. And mathematicians who can come up with elegant solutions but who are divorced from reality.

While you might make a career out of falling under any of the above categories, to truly unleash your potential as a quant, you should be able to do all. You should be a fox and should know each of these  tricks. And unlike the fox in the Old Russian fairy tale, the key to being a good fox is to know what trick to use when. Let me illustrate this with an example from my work today (actual problem statement masked since it involves client information).

So there were two possible distributions that a particular data point could have come from and I had to try and analyze which of them it came from (simple Bayesian probability, you might think). However, calculating the probability wasn’t so straightforward, as it wasn’t a standard function. Then I figured I could solve the probability problem using the inclusion-exclusion principle (maths again), and wrote down a mathematical formulation for it.

Now, I was dealing with a rather large data set, so I would have to use the computer, so I turned my mathematical solution into pseudo-code. Then, I realized that the pseudo-code was recursive, and given the size of the problem I would soon run out of memory. I had to figure out a solution using dynamic programming. Then, following some more code optimization, I had the probability. And then I had to go back to do the Bayesian analysis in order to complete the solution. And then present the solution in the form of a “business solution”, with all the above mathematical jugglery being abstracted from the client.

This versatility can come in handy in other places, too. There was a problem for which I figured out that the appropriate solution involved building a classification tree. However, given the nature of the data at hand, none of the off-the-shelf classification tree algorithms for R were ideal. So I simply went ahead and wrote my own code for creating such trees. Then, I figured that classification trees are in effect a greedy algorithm, and can lead to getting stuck at local optima. And so I put in a simulated annealing aspect to it.

While I may not have in depth knowledge of any of the above techniques (to gain breadth you have to sacrifice depth), that I’m aware of a wide variety of techniques means I can provide the solution that is best for the problem at hand. And as I go along, I hope to keep learning more and more techniques – even if I don’t use them, being aware of them will lead to better overall problem solving.

Why standard deviation is not a good measure of volatility

Most finance textbooks, at least the ones that are popular in Business Schools, use standard deviation as a measure of volatility of a stock price. In this post, we will examine why it is not a great idea. To put it in one line, the use of standard deviation loses information on the ordering of the price movement.

As earlier, let us look at two data sets and try to measure their volatility. Let us consider two time series (let’s simply call them “series1” and “series2”) and try and compare their volatilities. The table here shows the two series:

vol1 What can you say of the two series now? You think they are similar? You might notice that both contain the same set of numbers, but jumbled up.  Let us look at the volatility as expressed by standard deviation. Unsurprisingly, since both series contain the same set of numbers, the volatility of both series is identical – at 8.655.

However, does this mean that the two series are equally volatile? Not particularly, as you can see from this graph of the two series:

vol2

It is clear from the graph (if it was not clear from the table already) that Series 2 is much more volatile than series 1. So how can we measure it? Most textbooks on quantitative finance (as opposed to textbooks on finance) use “Quadratic Variation” as a measure of volatility. How do we measure quadratic variation?

If we have a series of numbers from a_1 to a_n , then the quadratic variation of this series is measured as
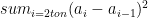
sum_{i=2 to n} (a_i - a_{i-1})^2

Notice that the primary difference feature of the quadratic variation is that it takes into account the sequence. So when you have something like series 2, with alternating positive and negative jumps, it gets captured in the quadratic variation. So what would be the quadratic variation values for the two time series we have here?

The QV of series 1 is 29 while that of series 2 is a whopping 6119, which is probably a fair indicator of their relative volatilities.

So why standard deviation?

Now you might ask why textbooks use standard deviation at all then, if it misses out so much of the variation. The answer, not surprisingly, lies in quantitative finance. When the price of a stock (X) is governed by a Wiener process, or

dX = sigma dW

then the quadratic variation of the stock price (between time 0 and time t) can be shown to be sigma^2 t , which for t = 1 is sigma^2 which is the variance of the process.

Because for a particular kind of process, which is commonly used to model stock price movement, the quadratic variation is equal to variance, variance is commonly used as a substitute for quadratic variation as a measure of volatility.

However, considering that in practice stock prices are seldom Brownian (either arithmetic or geometric), this equivalence doesn’t necessarily hold.

This is also a point that Benoit Mandelbrot makes in his excellent book The (mis)Behaviour of Markets. He calls this the Joseph effect (he uses the biblical story of Joseph, who dreamt of seven fat cows being eaten by seven lean foxes, and predicted that seven years of Nile floods would be followed by seven years of drought). Financial analysts, by using a simple variance (or standard deviation) to characterize volatility, miss out on such serial effects.

Stock market volatility spikes

The Indian stock markets have become especially volatile. Figure 1 shows the volatility of the Nifty in the last three years. As usual, we use a trailing 30-day quadratic variation as a measure of volatility. Don’t bother about the units of the y-axis, just look at the relative movement.

Source: Yahoo
Source: Yahoo

Notice that the volatility levels we have seen in the last month or so are unprecedented in the last three years. Let us take a closer look:

Source: Yahoo
Source: Yahoo

This gives us a better picture. Volatility was well under control till mid-August, when it started rising (since we use a 30-day trailing QV, this means that markets started getting choppy in mid-July). The volatility is now at an all-time high.

However, the official volatility index (India VIX) disagrees. According to this, volatility has actually dropped from its all-time high. The VIX also looks significantly choppy.

Source: NSE
Source: NSE


Perhaps this indicates some trading opportunity in options?

Anscombe’s Quartet and Analytics

Many “analytics professionals” or “quants” I know or have worked with have no hesitation in diving straight into a statistical model when they are faced with a problem, rather than trying to understand the data. However, that is not the way I work. Whenever I set out solving a new problem, I start with spending considerable time trying to get a feel of the data. There are many things I do to “feel” the data – look at a few lines of data, look at descriptive statistics of some of the variables and distributions of individual variables. The most powerful tool, however, that lets me get a feel for data is the humble scatterplot.

The beauty of the scatter plot is that it allows you to get a real feel for the data. Taking variables two at a time, it not only shows you how each of them is distributed but also how they are related to each other. Relationships that are not apparent when you look at the data become apparent when you graph them. I may not be wrong in saying that the scatterplot defines the direction and scope of your entire solution.

The problem with the debate on how analytics needs to be done is that it is loaded. A large majority of people who use statistics in their daily work dive straight into analysis without looking at the data. Perhaps they deem that looking at data is a waste of time? I have even seen pitch decks by extremely reputed software companies that propose solutions such as “we will solve this problem using Logistic Regression” without even having seen the data.

Let us take an example now. Take the following four data sets (my apologies for putting an image here):

source: http://lectorisalutem.wordpress.com/2011/11/17/anscombes-quartet/

Let us say you dive straight into the analysis. Like a good “analytics professional” you dive straight into regression. You may even do some descriptive statistics for each of the data sets along the way. And this is what you find (again, apologies for the image)

Source: http://lectorisalutem.wordpress.com/2011/11/17/anscombes-quartet/

Do you conclude that the four data sets are the same? Pretty much identical statistics right? I wouldn’t be surprised if you were to publish that there is nothing to differentiate between these four data sets. Now, let us do a simple scatter plot of each of these data sets and check for ourselves:

Source: http://lectorisalutem.wordpress.com/2011/11/17/anscombes-quartet/

Now, do you still think these data sets are identical? Now you know why I stress so much upon getting a feel for the data and drawing the humble scatter plot?

The data set I’ve used here is a rather famous one, and it is called Anscombe’s Quartet. The purpose of the data set is to precisely describe what I have in this post. That one needs to get a feel for the data before diving into the analysis. Draw scatter plots for every pair of variables. Understand the relationships, and let this understanding guide your further analysis. If one were able to perfectly analyze every piece of data by diving straight into a regression, the job of analytics might as well be outsourced to computers.

PS: it is a tragedy that when they teach visualization in school they don’t even mention the scatter plot. At a recent workshop I asked the participants to name the different kinds of graphs they knew. “Line”, “Bar” and “Pie” were the mots common answers. Not one answered “scatter plot”. Given the utility of this simple plot this is indeed tragic.

Exponential increase

“Increasing exponentially” is a common phrase used by analysts and commentators to describe a certain kind of growth. However, more often than not, this phrase is misused and any fast growth is termed as “exponential”.

If f(x) is a function of x, f(x) is said to be exponential if and only if it can be written in the form:

f(x) = K alpha ^x

So if your growth is quick but linear, then it is not exponential. While on the topic, I want to point you to two posts I’ve written on my public policy blog for Takshashila: one on exponential growth in bank transfers that I wrote earlier today and another on exponential growth in toilet ownership. The former shows you how to detect exponential growth and in the latter I use what I think is an innovative model to model toilet growth as exponential.

Exponential increase in uptake of IMPS

We had dealt with exponential increases on this blog once before. We revisit the topic, and this time this is in the context of the inter bank mobile payment system that came into place sometime last year. I’ve never used it so I’m not sure how it works, but going by the data put out by the National Payments Corporation of India, the volume of transactions is increasing at an exponential rate.

How do we determine this is an exponential rate? First, let us look at the time series of total volumes of transactions:

Source: http://www.npci.org.in/impsVolumes.aspx

Notice that after remaining flat for a couple of months (maybe even decreasing) the number of transactions has really taken off (March is probably an aberration – but given that it’s the month of financial closure the higher volumes can be expected). Increased exponentially, you say? How can we test that?

We can test that by using a logarithmic scale for the y-axis. Here is the same plot again, except that this time the Y-axis is logarithmic.

Source: http://www.npci.org.in/impsVolumes.aspx

Notice that apart from the part with the aberration and the initial two months, the graph is now linear. In other words, we can describe this graph by a line of the form

log y = a + b x

or y = exp (a + bx)

Thus, exponential!

Coming back from the geekery, it is really good to note that IMPS has taken off. However, this should not be taken as proof of the fact that mobile payments are easy, for IMPS is anything but easy. New RBI Governor Raghuram Rajan has said in his inaugural speech that he hopes to make it simpler to make payments via mobile. Hopefully this will take off soon. Till then all we can do is to contribute to the exponential growth in the update of the IMPS!

Coase

In the wake of the passing of Ronald Coase, two incidents, both professional. The first was with an established company to whom I suggested a partnership – they are in a space where I don’t have much skill, but have access to companies who I would love to sell to, and they don’t have my skill and our skills are complementary. So I reached out to them (through common contacts) suggesting that we could work together. They came back to me saying they would love to work with me, but would want me to join them as an employee.

The second was an incoming lead. This was a rather small company doing something similar to what I’m doing but with bigger ideas. They want me to join this “innovation hub” they are trying to create. This is a loose federation they are creating including professionals from various fields. Nobody is obliged to work full time for the hub, but this gives people an opportunity to get together and work together on projects where their respective expertise can combine well.

As the more perceptive of you who would have read every Coase obituary in the last two weeks would have figured out, the piece of work that Coase is most well known for is about the theory of the firm. The question is rather simple – why should you and I get together and form a firm if we have to work together, if we can remain independent and just come together for projects. The answer lies in transaction costs.

The advantage of coming together as a firm is that you negotiate only once. Let us suppose you are a graphic designer and I’m a data scientist. If we decide to work together on a visualization project, how do we decide how much you get and how much I get? We will need to negotiate. Let’s say we negotiate and agree on a price. And complete a project and split the spoils. What would happen the next time we were to bid for a project? We will need to negotiate again on how we will share the spoils.

If on the other hand we were to form a partnership firm, then for every project that we do, our respective share is fixed! Thus we don’t have to negotiate before every single projects. Thus, firms exist so that you don’t have to repeatedly negotiate.

However, there is a downside to this. What if I form a firm with a graphic designer, and then we see a significant opportunity in projects that involve a lot of analysis but little visualization? In that case, I have no use of my partner, and would loathe to pay him his share of the profits. Or consider if I were to somehow become much better at my job, while my partner stagnates. There is little I can do, for we’ve been locked in into the financial arrangement.

These are only some of the complications that arise when you need to decide whether you want to become a firm. I just thought it is pertinent that I’m having some of these dilemmas (employee versus consultant versus partner versus member of federation) in the few weeks after Coase’s passing.

Would you want a free membership card?

Last weekend I was at Cafe Coffee Day on MG Road, waiting to meet a prospective client, when one of the store staff walked up to me with a card. “This is a free loyalty card, Sir”, he said, going on to tell me that if I were to buy three coffees using the card I would stand to get a free additional coffee. Considering that Cafe Coffee Day is my favourite meeting room, I thought it might make sense to use the card.

You might have noticed this in supermarkets, too. Invariably you get asked if you want a free membership card. In case you tell them that you had taken a card but are not carrying it, they offer to find your card number for you based on your phone number. Given that it probably costs the store to issue these cards (cost of cards, maintenance, staff time, cost of rewards), there must be a good reason that they are so eager to give it to you for free.

What separates traditional retail from modern is that in the latter, there are way too many customers who visit a store, and way too many store staff who attend to them. Consequently, it is hard for store staff to know who is a regular, and what the regular customers want. You might go up to your regular “single store” bar, and the barman might start mixing your favourite drink as soon as he sees you pop in. In a chain such as Cafe Coffee Day, however, such information is not forthcoming.

What loyalty cards enable stores to do is to track repeat purchases. You might be buying a kilo of rice every week at the neighbourhood supermarket, but in most cases there is no way for the supermarket to know it is you who bought the rice each time. Once you have a card and your sales are logged to that each week, the store knows how often you visit and what kind of items you are likely to buy together. Loyalty cards allow the store to “profile” you and thus hope to serve you better. The cost of the card is small compared to the value of the information the store gets about you.

A new trend in loyalty cards is “third party cards” that work across stores. These cards are issued by independent third party vendors and multiple stores subscribe to them. The advantage with these cards is that the third party has information about the customer across retailers. So for example, it makes it possible for the vendor to know the brand of formal shirts that people who buy Levi’s Jeans buy.

While this is a dream from an analyst’s viewpoint, the uptake of such cards so far has been low. I know of at least one company in this area that folded up and another that is not doing too well. Hopefully this trend will reverse soon and we will find one player who manages to scale up and issue cards at lots of retailers.

Wheat Prices in India

The ministry that has taken the greatest enthusiasm in disseminating data via the data.gov.in data portal launched by the government of India is the Ministry of Agriculture, which has so far released over 1700 different data sets. Once you download the data you will find that the data is extremely extensive.

I happened to download data on wheat prices in the last four years and the level of detail is amazing. For each agricultural market in the country, for each kind of wheat, it gives the minimum, maximum and modal traded price of wheat for every day. Over the four years, the data set has over 6 lakh data points.

I wanted to look at how the wholesale price of wheat has varied in the last four years. Rather than get into the nittygritties of different varieties of wheat and different markets, I simply took the median traded price of wheat for each day and plotted them. While there might be different varieties whose prices vary from each other, the median is enough to give us a level.

wheatprice

Notice the seasonality in the price of wheat. Given that wheat is primarily a Rabi crop, you would expect the new harvest to hit the markets sometime around March-April (Baisakhi is the primary Rabi harvest festival). However, if you look at the price trends, you notice that the price peaks each year around December, and the price drops starting in January. It continues to drop until March-April after which it starts rising again.

The data shows that there was a steep increase in the price of wheat towards the end of 2009. 2011, however, didn’t behave similarly, with a sharp drop in the price of wheat towards the end of the year. The latter, however, has been more than compensated by the sharp increase in the price of wheat through the course of 2012.

There is a lot more you can play around with the data. You can expect some more agricultural analysis on this blog in the coming weeks or months.

Modi and Advani

Here’s how I think the BJP should’ve reacted to the fact that LK Advani wasn’t too happy about Narendra Modi being announced as their candidate for Prime Minister in next year’s elections.

Yes, Mr. Advani is still not on board yet. However, we are a democratic party and there was strong demand from an overwhelming majority of our party workers that Mr. Modi’s name be announced as the Prime Ministerial candidate. As in any democratic process, there will be the minority who will not be happy, but we are sure that they (including Mr. Advani) will respect the democratic process and extend their support to Mr. Modi.